Flux Knowledge Base Platform
Flux data governance platform based on AI large models, VLM visual language large models, big data and other technologies, focusing on enterprise-level knowledge data governance scenarios, gathering fragmented knowledge data of enterprises, and extracting high-quality knowledge, making unstructured data truly flow, and realizing the digital transformation of enterprises.
Core function
Provide stable, efficient, and secure functional capabilities around core business processes to help enterprises quickly complete product landing and continuous operation.
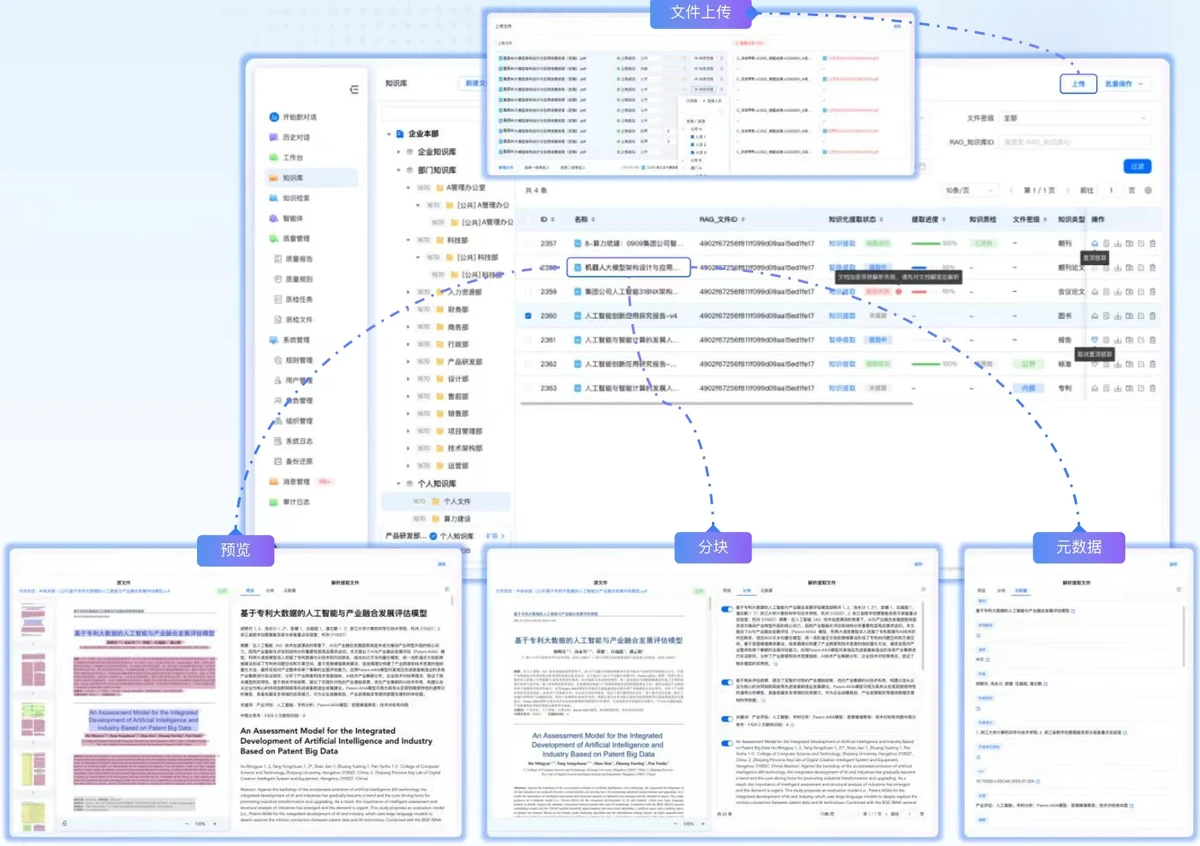
Extraction of multi-source and heterogeneous data
Supports OCR extraction and layout restoration for more than 10 formats such as PDF, images, and scanned copies, automatically retrieves metadata, tables, and formulas, and realizes high-quality入库 of multi-source knowledge.
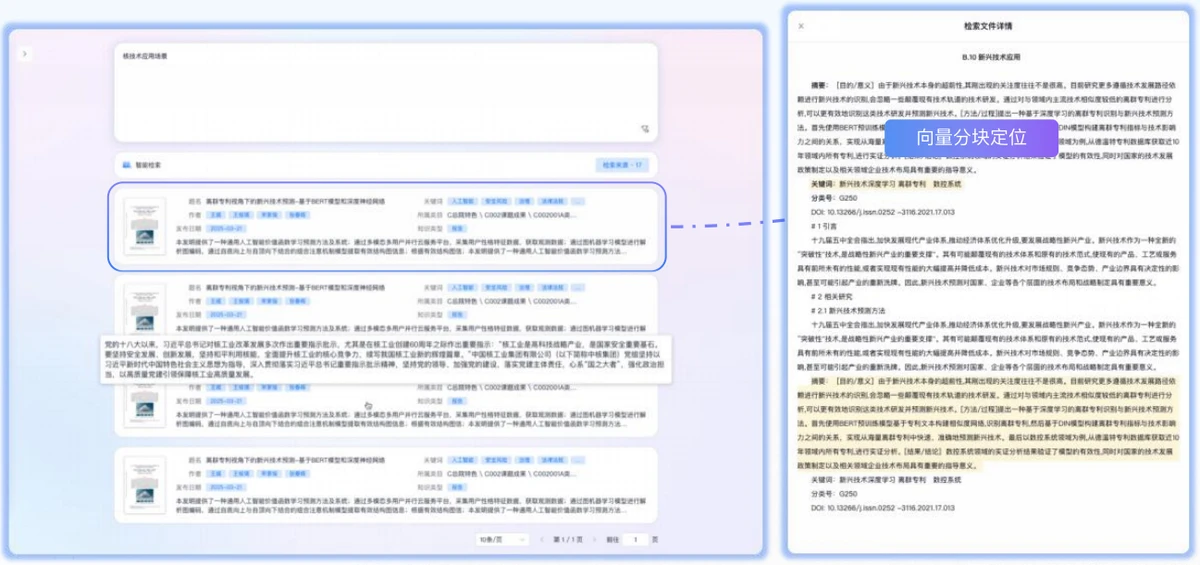
Intelligent semantic vectorization
Utilizes AI large models for intelligent segmentation and vectorization processing of knowledge, constructs semantic-level cross-modal retrieval capabilities, and achieves accurate knowledge positioning and efficient recall.
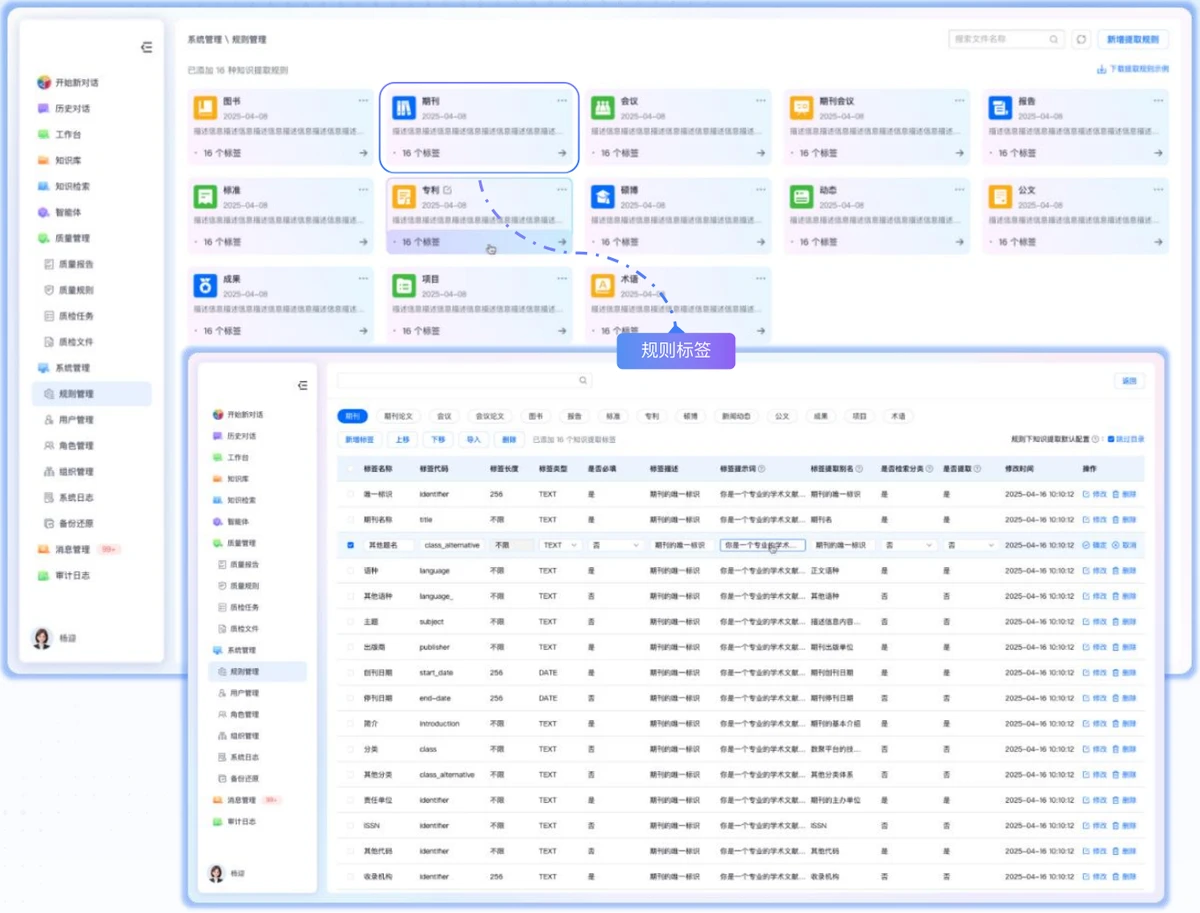
Intelligent annotation classification
AI agents automatically label and classify knowledge according to preset metadata rules, replacing manual annotation, significantly reducing knowledge governance costs and annotation errors.
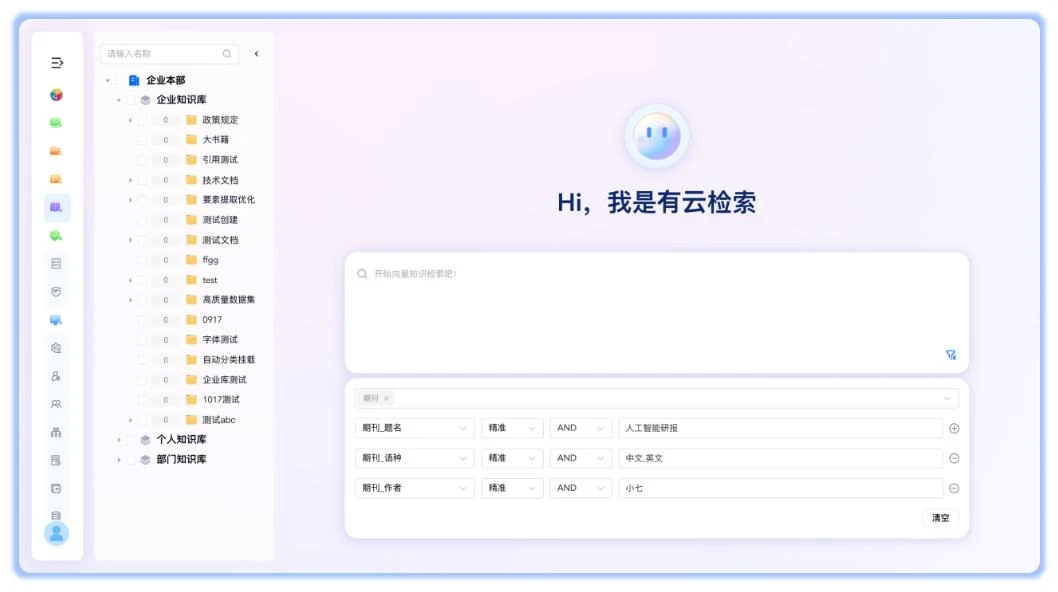
Intelligent Knowledge Question and Answering
Based on RAG retrieval enhancement generation, supports natural language questioning to quickly locate corporate knowledge and provide evidence-based answers, making knowledge readily available and fully realized in value.
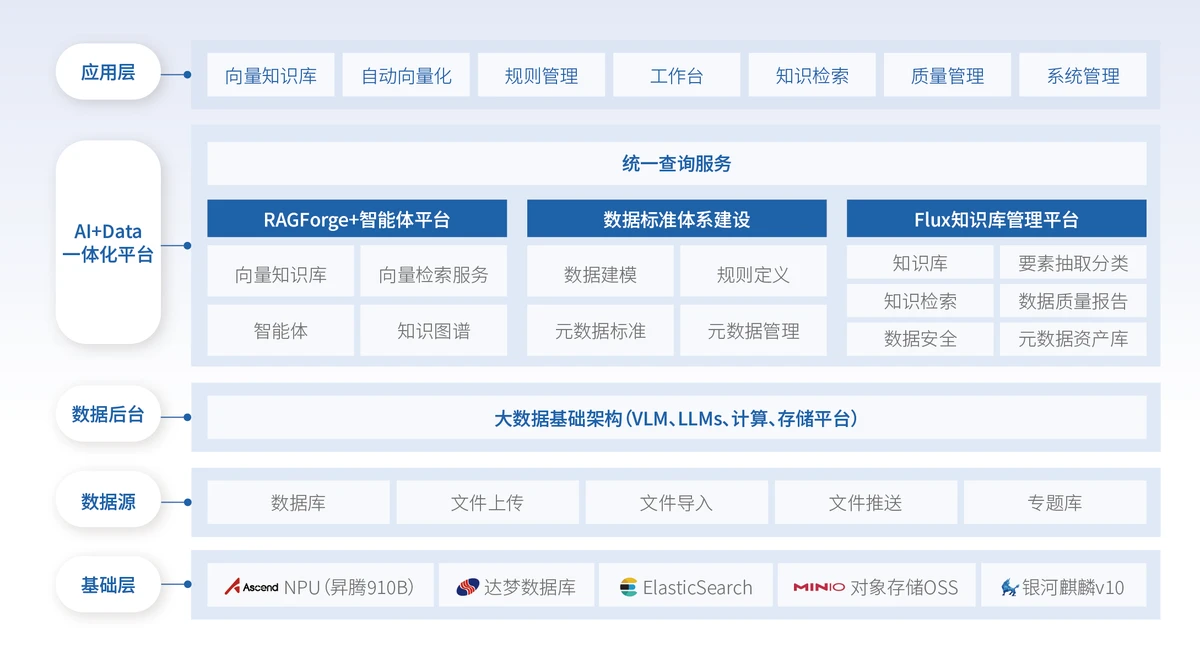
Product architecture
Carry core capabilities with modular architecture, taking into account system stability, elastic expansion, and multi-scenario integration requirements.
Product highlights
Focus on performance, security, ease of use, and scalability, continuously enhancing the comprehensive value of the product in complex business scenarios.
Multi-source Heterogeneous Extraction
Supports OCR extraction and layout restoration for more than 10 file formats such as PDF and images, automatically retrieves metadata, text, tables, and formulas, with an accuracy rate of over 95%.
Intelligent Vectorization
Based on AI large model block and vectorization technology, converts unstructured knowledge into high-dimensional vectors, achieving semantic cross-modal retrieval and locating massive knowledge in seconds.
Intelligent Agent Annotation
The intelligent annotator automatically labels, classifies, and stores data according to metadata rules, the quality inspector performs secondary verification, the labeling coverage is over 90%, and the data quality is improved by 30%.
Empowerment of knowledge application
Provide RAG-enhanced knowledge Q&A and knowledge writing capabilities, improve knowledge utilization by 50%, and provide a knowledge system for GenAI scenarios such as enterprise office and model fine-tuning.
Application scenario
Suitable for various business and industry scenarios, helping organizations quickly build replicable and scalable digital application capabilities.
Enterprise document knowledge governance and intelligent retrieval
Manufacturing, energy, finance and other large enterprises have accumulated a huge amount of unstructured documents such as PDFs, scanned copies, images, tables, etc., and manual search efficiency is extremely low. The platform extracts multi-source and heterogeneous documents (10+ formats) and converts them into structured knowledge, achieving semantic-level retrieval with the function of "finding related documents with one sentence", allowing the data "lying on the hard disk" to truly circulate.
Financial compliance and risk control document management
Banks, securities and other financial institutions need to strictly manage compliance systems, audit reports, contract agreements and other documents. Traditional manual inspections are inefficient and incomplete. The platform's AI intelligent labeling automatically classifies and archives, intelligent quality inspection double-checks for errors and omissions, knowledge questions quickly locate compliance clauses, and support supervision inspections and internal audits.
Government archives digitalization and knowledge services
The government department faces a large number of historical archives and current policy documents, the platform will extract OCR, page restoration and vectorized storage from paper scanning copies and unstructured files, build a government knowledge graph, support internal knowledge question and answer, policy reasoning and decision-making assistance.
Enterprise R&D knowledge accumulation and reuse
Science and technology enterprises produce a large number of design documents, experimental reports and patent literature during the R&D process, the platform knowledge graph will connect fragmented knowledge into a network, support RAG enhanced R&D knowledge question and answer and writing assistance, reduce redundant research, and accelerate technological iteration.